


 buy artwork
 buy artwork
The art of Pi (`\pi`), Phi (`\phi`) and `e`


This section contains various art work based on `\pi`, `\phi` and `e` that I created over the years.
Some of the numerical art reveals interesting and unexpected observations. For example, the sequence 999999 in π at digit 762 called the Feynman Point. Or that if you calculate π to 13,099,586 digits you will find love.
`\pi` day art and `\pi` approximation day art is kept separate.

If you look hard enough, you can find anything.
In this case, you can find names of famous mathematicians and even the digits of mathematical constants in the digits of `\pi`. These posters are very similar to the Love in `\pi` series I did for the 2013 `\pi` day.
To "find" instances of text in `\pi`, you first need a way to represent letters numerically.
To do this, I arbitrarily map A to 1, B to 2 and so on. A space is a zero. Thus the string "HELLO" becomes 85121215, because H=8, E=5, L=12 and O=15. Here I don't pay attention to the case of the letters.
It turns out that the first "HELLO" in `\pi` is at position 34,851,875.
...05419663858273297437 85121215 18330978282693807709...
You can find your own favourite sequence using the The `\pi` search page.
One of the posters in this section indicate the position of the last names of 135 famous mathematicians: Abel, d'Alembert, Apollonius, Archimedes, Archytas, Aristotle, Aryabhata, Atiyah, Babbage, Banach, Banneker, Bernoulli, Bhascara, Birkhoff, Boole, Borel, Brahmagupta, Brouwer, Brunelleschi, Cantor, Cardano, Cartan, Cauchy, Cavalieri, Cayley, Chebyshev, Chern, Cohen, Conway, Dedekind, Democritus, Descartes, Diophantus, Dirichlet, Einstein, Eisenstein, Eratosthenes, Erdos, Escher, Euclid, Eudoxus, Euler, De Fermat, Fibonacci, Fourier, Frege, Galilei, Galois, Gauss, Germain, Godel, Grassmann, Grothendieck, Hadamard, Halley, al-Haytham, Hamilton, Hardy, Hausdorff, Hermite, Heron, Hilbert, Hipparchus, Hopper, Hui, Huygens, Hypatia, Jacobi, Jordan, Kepler, Khayyam, al-Khwarizmi, Klein, Kolmogorov, Kummer, Lagrange, Lambert, Laplace, Lasker, Lebesgue, Legendre, Leibniz, Lie, Liouville, Littlewood, Lorenz, Lovelace, Madhava, Magnus, Maxwell, Minkowski, De Moivre, Monge, De Morgan, Napier, Nash, Von Neumann, Newton, Noether, Pacioli, Panini, Pappus, Pascal, Peano, Perelman, Plato, Plucker, Poincare, Poisson, Polya, Poncelet, Ptolemy, Pythagoras, Ramanujan, Riemann, Robinson, Russell, Selberg, Serre, Siegel, Steiner, Sylvester, Tao, Tarski, Taylor, Thales, Turing, Venn, Viete, Wallis, Weierstrass, Weil, Weyl, Whitehead, Wiles, Witten.
The search is limited to the first 1,000,000,000 digits of `\pi` and if the sequence of digits that corresponds to the name isn't found then I trim the last letter off the name and try again.
For example, "Chebyshev" which is 385225198522 is not found but the next attempt "Chebyshe" 3852251985 is found at digit 7,737,114.
...50964281262402457441 3852251985 89678438272780298551...
The other poster shows the location of 210 mathematical constants. Here the search doesn't require encoding—the search query is the the sequence of digits in the constant. The leading zero before the decimal for constants `\lt 1` is trimmed. If the sequence isn't found (I use the precision as listed on the Wikipedia page), I trim the last digit and repeat.
For example, Euler's number 2.71828182 is found at digit 246,890,641.
...22156499305 271828182...
Consequences of missing data
Either I've been missing something or nothing has been going on. —Karen Elizabeth Gordon
Missing data are everywhere. Subjects may decline to participate in a survey or fail to answer sensitive questions. A cell culture might fail due to contamination. Instrument failures or mishandling of a sample may lead to missing observations. But why are missing data a problem?
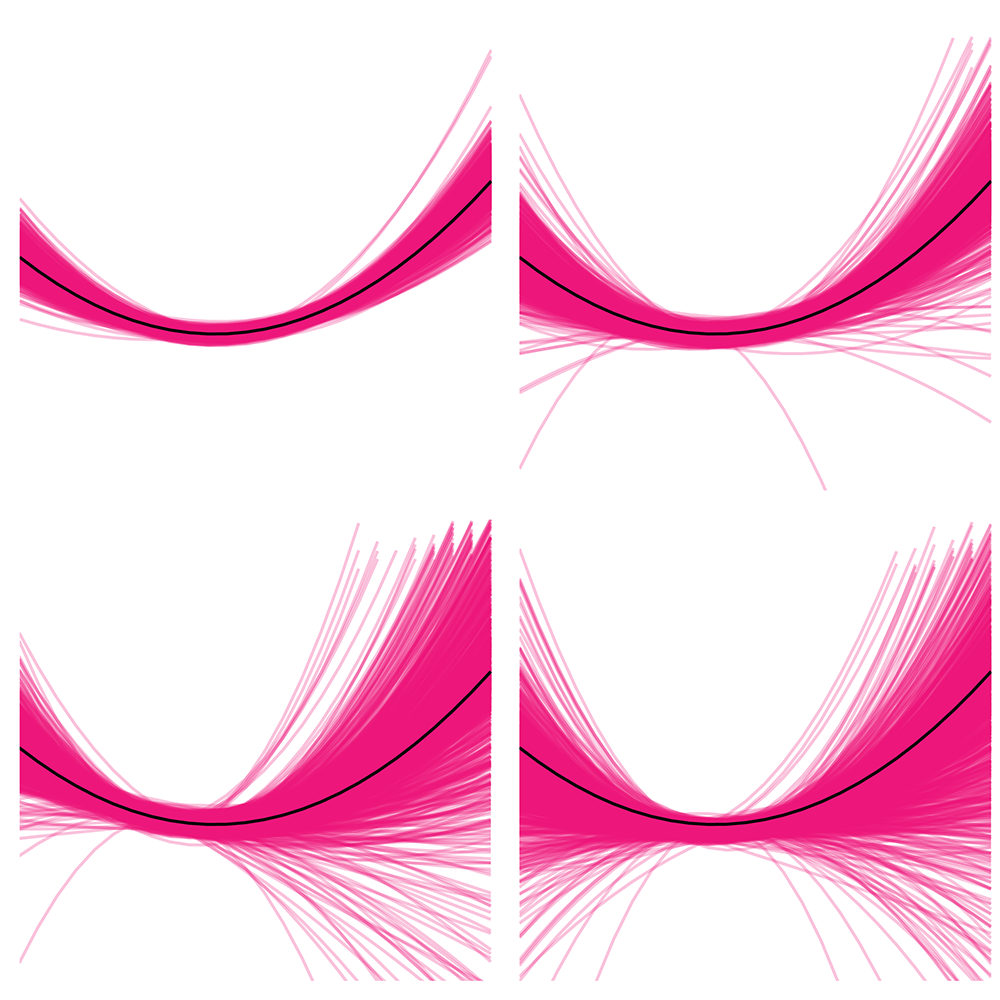
This month, we begin a series of articles about practical and statistical aspects of missing data. We'll see that missing data can increase variability and introduce bias and we will ask whether anything can be done to mitigate these consequences. It turns out that, in the case where we know nothing about the missing subjects, no mitigation is possible. We must accept higher variability and, if we have a suspicion that the missing subjects aren’t completely random, possible bias as well.
Tanujit Dey, T., Lipsitz, S.R., Fitzmaurice, G., Krzywinski, M. & Altman, N. (2026) Points of significance: Consequences of missing data. Nat. Methods 23 (in print).
Double Robustness
It is not certain that everything is uncertain. —Blaise Pascal
We have already explored how we can mitigate bias caused by confounding variables in observational studies using propensity score (PS) matching (PSM) and propensity score weighting (PSW). However, any statistical model is only as good as its assumptions and, if it is specified incorrectly, it can itself produce biased estimates of the treatment effect.
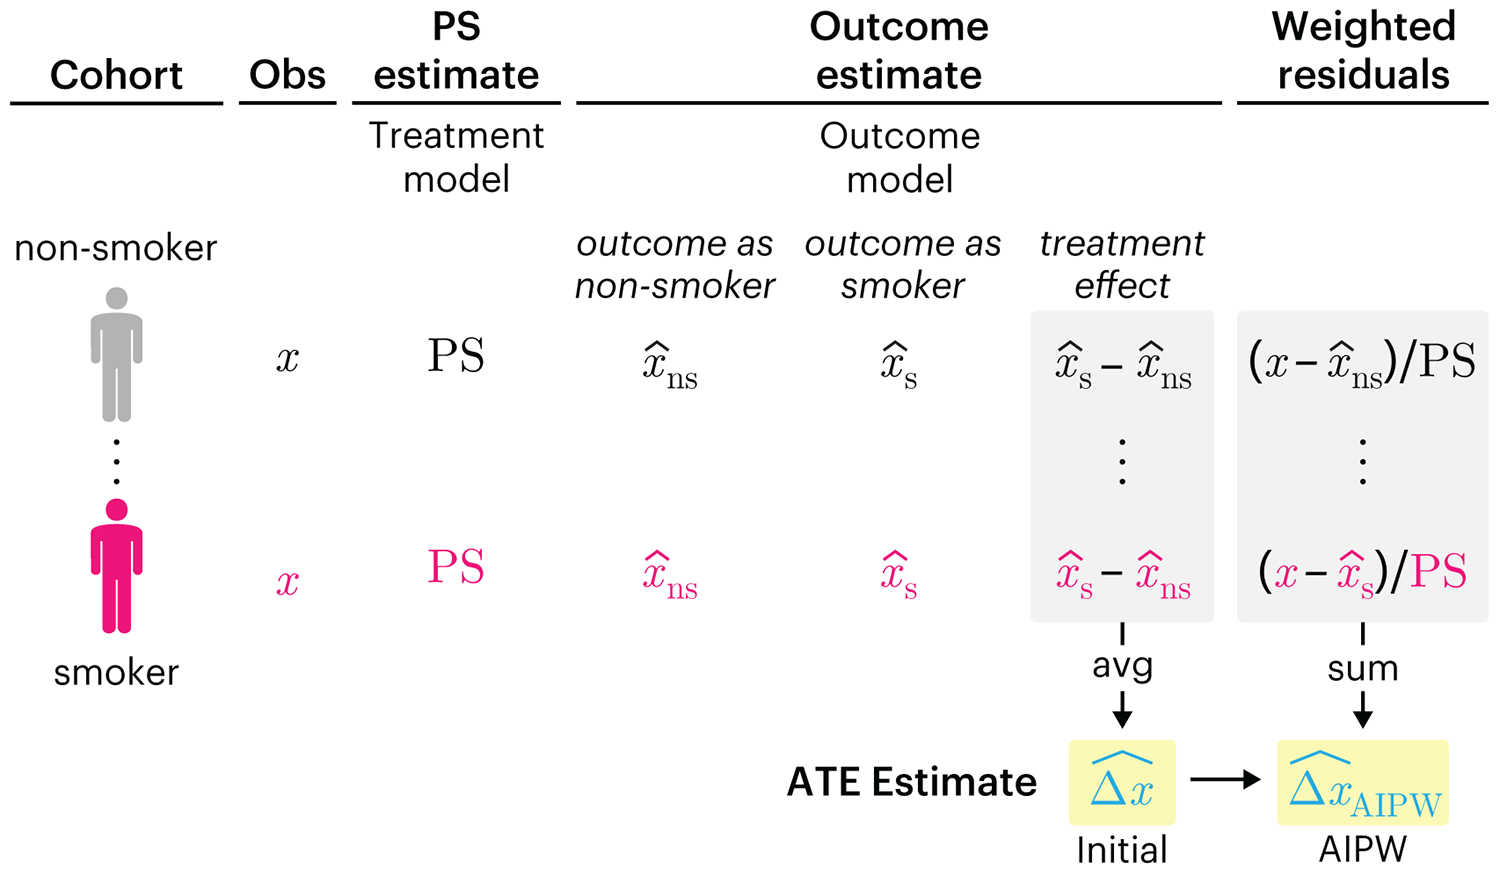
This month, we explore double robustness, a powerful statistical concept that provides a valuable “safety net” against the risk of an incorrect model. It offers two opportunities, instead of just one, to obtain a valid estimate of the treatment effect — making it possible to draw credible causal inferences from observational data without having to depend on a single set of modeling assumptions.
Kurz, C.F., Krzywinski, M. & Altman, N. (2026) Points of significance: Double Robustness. Nat. Methods 23:868–869.
Nature Biotechnology cover
My cover design on the 7 April 2026 Nature Biotechnology issue shows the dendrogram that represents a cluster of uniquely expressed (or downregulated) genes in human naive stem cells induced from such cells. Within each dendrogram block, the genomic barcode sequence (sampled from Supplementary Table 1) is depicted with a Code 39 barcode. The highlighted barcode is one of those used for cell isolation.
Ishiguro S. et al. A multi-kingdom genetic barcoding system for precise clone isolation (2026) Nature Biotechnology 44:616–629.
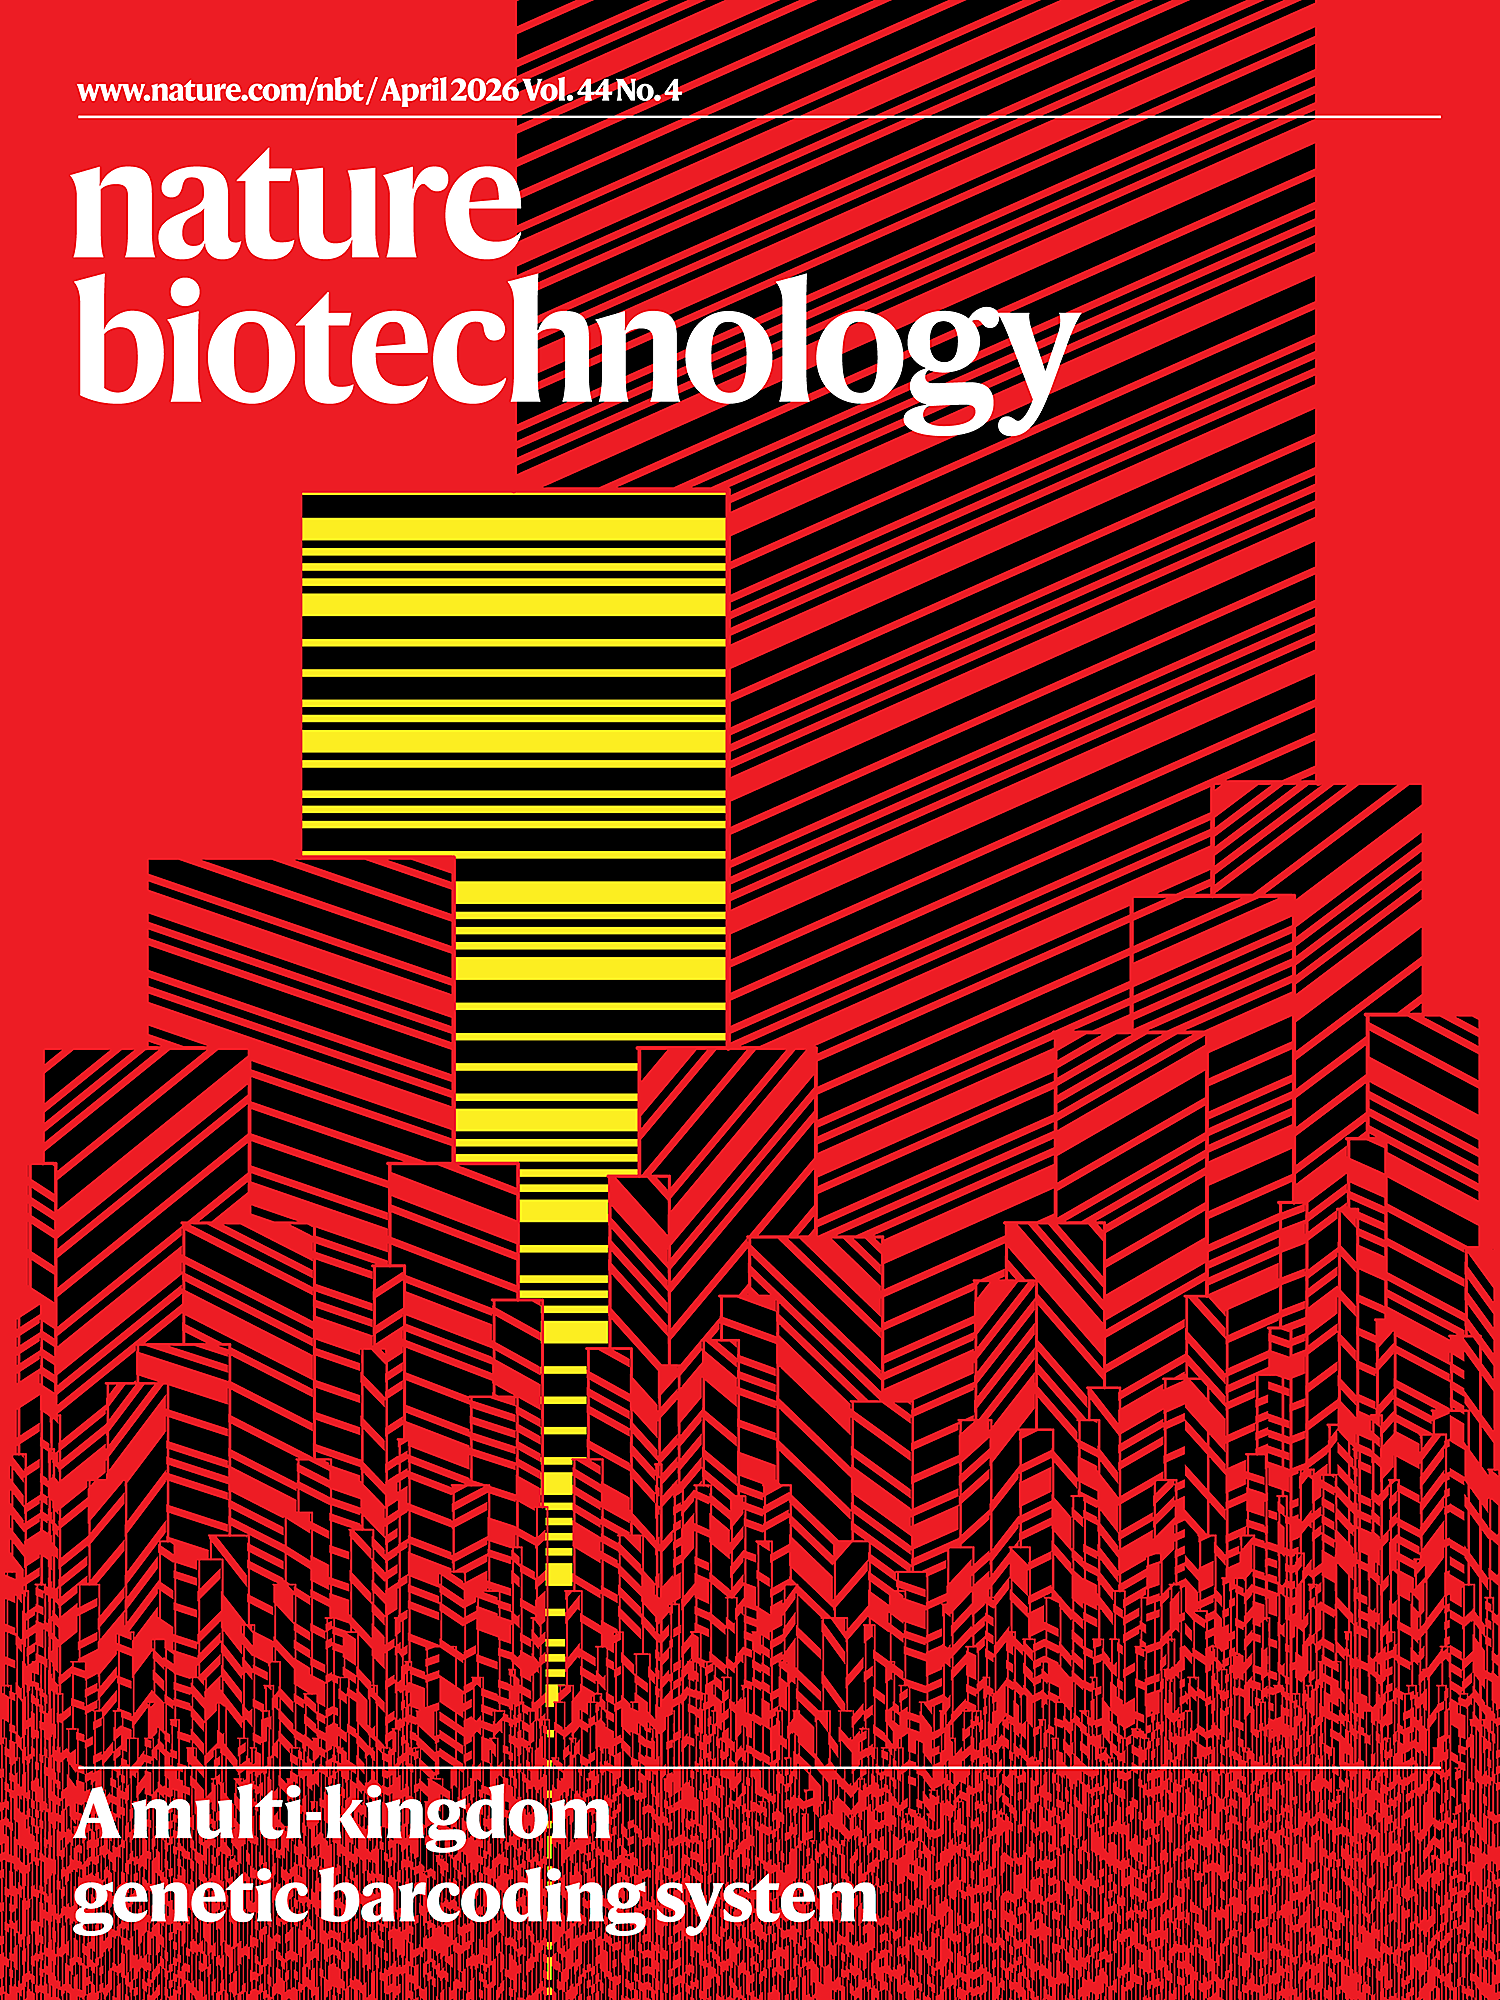
Browse my gallery of cover designs.
Happy 2026 π Day—
Art for the 5%
Celebrate π Day (March 14th) and enjoy the art — but only if you're part of the 5%.
Go ahead, see what you can't see.
Ishihara's Tests for Colour Deficiency
Authentic and accurate images of Ishihara's test plates photographed (and lovingly color-corrected) from the 38-plate Ishihara's Tests for Colour Deficiency.
I also provide the position, size, and color of each circle on each test plate.


Symmetric alternatives to the ordinary least squares regression
What immortal hand or eye, could frame thy fearful symmetry? — William Blake, "The Tyger"
This month, we look at symmetric regression, which, unlike simple linear regression, it is reversible — remaining unaltered when the variables are swapped.
Simple linear regression can summarize the linear relationship between two variables `X` and `Y` — for example, when `Y` is considered the response (dependent) and `X` the predictor (independent) variable.
However, there are times when we are not interested (or able) to distinguish between dependent and independent variables — either because they have the same importance or the same role. This is where symmetric regression can help.

Luca Greco, George Luta, Martin Krzywinski & Naomi Altman (2025) Points of significance: Symmetric alternatives to the ordinary least squares regression. Nat. Methods 22:1610–1612.